
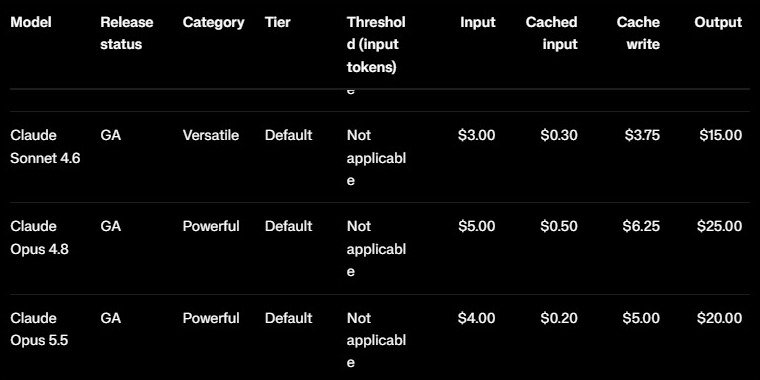
Microsoft says its new MAI Code 2 reaches 96% of Claude Opus 5.5 performance at 5% of the cost. We checked GitHub’s official price table: per token, MAI Code 2 output costs $2.50 per 1M against $20 for Opus 5.5, which is 8x cheaper, and 4x after 17 May 2027. The story had over 360 points and 155 comments on Hacker News (18 Nov).
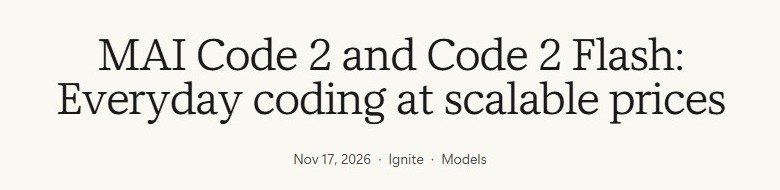
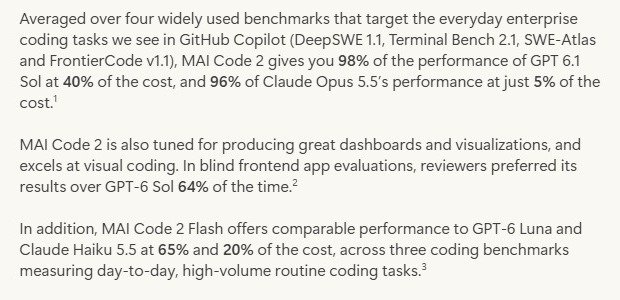
The “5%” is real in Microsoft’s own test, but it is not the price per token.
The facts
- Two models. Code 2 targets multi-file implementation, deep debugging, repo-wide reasoning and UI. Code 2 Flash targets code explanations, targeted edits and routine fixes. Source: Microsoft AI.
- The claim. Over 4 benchmarks: 98% of GPT 6.1 Sol at 40% of the cost, 96% of Opus 5.5 at 5%. Flash: comparable to GPT-6 Luna and Haiku 5.5 at 65% and 20%. Same source.
- Fine print. Maximum reasoning effort, three benchmarks on Microsoft’s internal MSBench, and the cost shown is the 50% promotional price. Same source.
- The limit. “Explicitly not yet tuned for harder problems, like fundamental science research and very long horizon agentic work.” Same source.
- Plans. Code 2: Copilot Pro, Pro+, Max, Business, Enterprise. Flash: also Free and Student. Both for eligible subscribers “on annual plans”, usage-based billing. Source: GitHub changelog.
Price per 1M tokens
| Model | Input | Output |
|---|---|---|
| Claude Opus 5.5 | $4.00 | $20.00 |
| GPT-6.1 Sol | $2.00 | $10.00 |
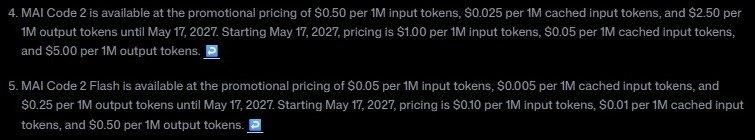
| MAI Code 2, promo | $0.50 | $2.50 |
| MAI Code 2, from 17 May 2027 | $1.00 | $5.00 |
| Claude Haiku 5.5 | $0.10 | $0.50 |
| GPT-6 Luna | $0.10 | $0.50 |
| MAI Code 2 Flash, promo | $0.05 | $0.25 |
| MAI Code 2 Flash, from 17 May 2027 | $0.10 | $0.50 |
Source: GitHub Docs, Models and pricing, 18 Nov. Our arithmetic: output is 8x cheaper than Opus 5.5 now, 4x later. Against GPT-6.1 Sol, 4x now and 2x later. At full price Flash costs the same per token as Haiku 5.5 and GPT-6 Luna.
What it changes
App developers: the model picker is the whole migration. Routine work is where a cheaper model can pay off. Billing is usage-based, so check your own bill.
Game developers and gamers: Microsoft’s blind test included games and 3D scenes, but it is Microsoft’s test. Try it on a prototype. Flash is listed for the Free plan, but read the “annual plans” line first.
Solo founders and anyone delegating to agents: the 20x gap (5%) is cost per task, while per token it is 8x, then 4x. The rest would come from fewer tokens per task, which is our inference, not Microsoft’s statement. For a long autonomous run, keep the top model. For short, bounded jobs, it is a fair experiment.
Who loses: nobody on paper, except that the discount ends. Budget for double.
How to pick it
- Open the model picker in your Copilot client (VS Code, Visual Studio, Copilot CLI, JetBrains and others in the changelog list).
- Look for MAI Code 2 or Flash. If missing, check your plan, the annual plan condition and, on Business or Enterprise, your admin settings.
- Select it and run a task whose answer you already know, then compare with your usual model.
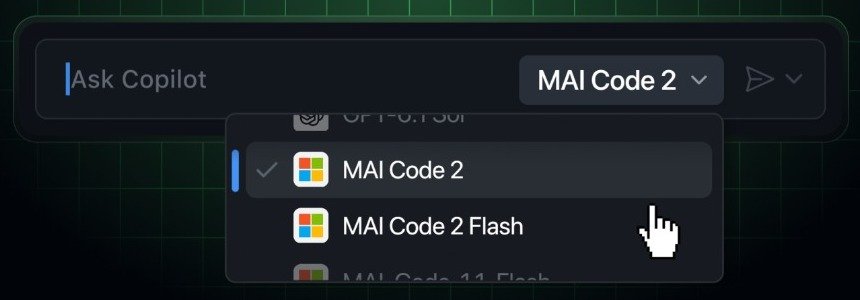
Flash for explanations and small edits. Code 2 for multi-file work and UI. The top model for long agent runs.
Our take
We did not test the model, so we cannot confirm the 96%. The benchmarks are Microsoft’s, at half price. The per-token gap is real and checkable, and trying it costs little. Ignore it if your work is long autonomous agent runs.
Sources
- Microsoft AI, “MAI Code 2 and Code 2 Flash” (17 Nov 2026). Primary source.
- GitHub changelog
- GitHub Docs, Models and pricing
- Hacker News discussion (over 360 points, 155 comments, 18 Nov).