
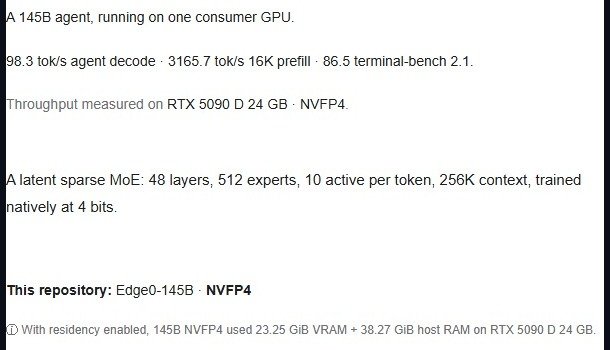
Edge0 says its 145B open-weights model “runs locally on a compatible laptop, with reported peak memory of 29GB”. The model card measures 23.25 GiB of VRAM plus 38.27 GiB of host RAM, on a desktop RTX 5090 D.
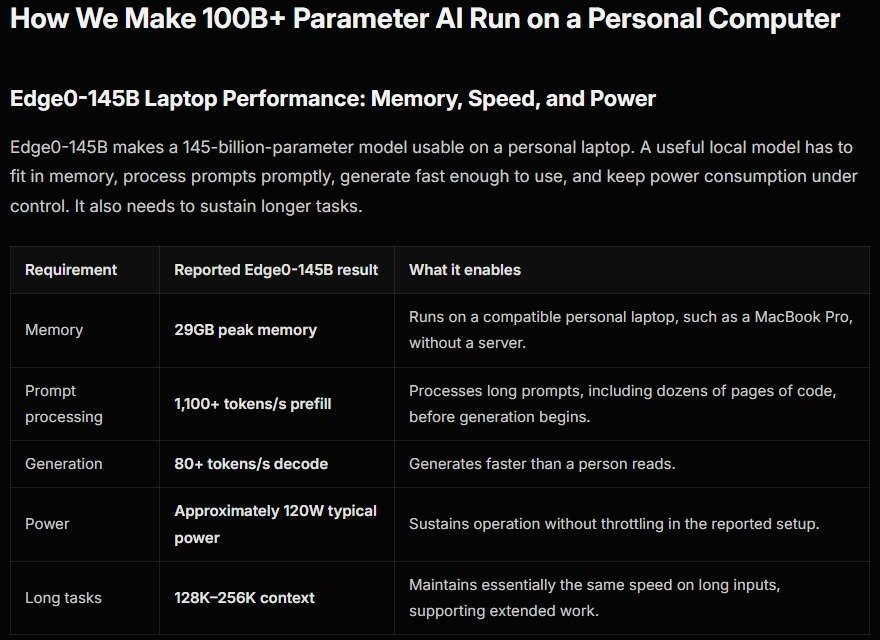
Both numbers can be true, but the sources never say exactly what the 29GB measures. The gap decides whether you can run it. This is our reading of the sources. We did not run the model ourselves.
The facts
- The claim. 145B parameters, about 10B active per step, “29GB peak memory”, decoding above 80 tokens/s, per the Edge0 announcement (12 Nov). The same post says “28GB” further down, and “a 48GB laptop”.
- Three tiers. “Hot experts” sit on the GPU, “an expert library of approximately 40GB sits in system memory”, and “approximately 48GB of vocabulary data resides on the SSD and is read on demand”, per the same post. So 29GB is a peak, not the size of the model.
- The card. NVFP4 weights are 47.79 GiB. Q3_K weights are 40.81 GiB (23.14 GiB VRAM plus 31.28 GiB RAM). Per the model card.
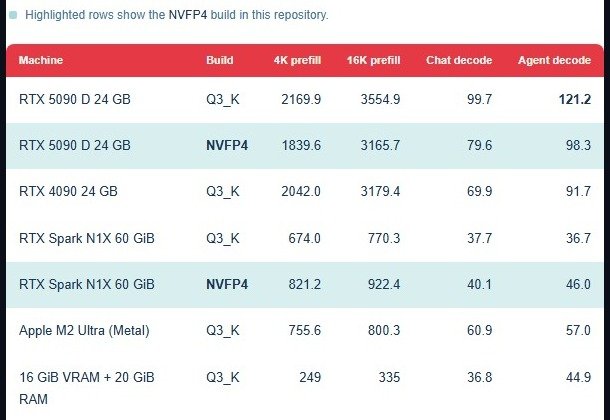
- Speed. The headline figures are measured on “RTX 5090 D 24 GB”, per the card. No machine in the speed table is labelled a laptop.
What it changes
Hardware, as listed on the model card (tok/s, chat decode / agent decode):
| Machine | Build | Chat | Agent |
|---|---|---|---|
| RTX 5090 D | Q3_K | 99.7 | 121.2 |
| RTX 5090 D | NVFP4 | 79.6 | 98.3 |
| RTX 4090 | Q3_K | 69.9 | 91.7 |
| RTX Spark N1X, 60 GiB | Q3_K | 37.7 | 36.7 |
| RTX Spark N1X, 60 GiB | NVFP4 | 40.1 | 46.0 |
| Apple M2 Ultra (Metal) | Q3_K | 60.9 | 57.0 |
| 16 GiB VRAM + 20 GiB RAM | Q3_K | 36.8 | 44.9 |
The last row is the same RTX 5090 D, which Edge0 capped to 16 GiB of VRAM and 20 GiB of RAM for the test. It is the closest the card gets to a smaller machine, and it still ran Q3_K at 36.8 tok/s chat decode. Now add up the card’s own numbers: 23.25 + 38.27 is about 61.5 GiB of fast memory for NVFP4, before the SSD part. That is why “laptop” needs the word “compatible”, and why we would not buy hardware on the 29GB figure.
Which build. Q3_K is smaller (40.81 vs 47.79 GiB) and faster on the 5090 D (99.7 vs 79.6 chat). It is also the build with Metal instructions for Apple Silicon, according to the card. NVFP4 is CUDA only. The card gives size and speed, so that is all we compare.
Start the server. You build edge0-infer from the repo first (the card links the build steps). Then the card gives one command:
edge0-infer serve --model /path/to/Edge0-145B-NVFP4
It prints “Listening: http://127.0.0.1:8000” and exposes OpenAI-compatible and Anthropic-compatible endpoints. Build steps are in the repo (Apache-2.0 for the framework code).
What the licence forbids. The model uses the Edge0 Community Model License 1.0 plus the Qwen Community License 1.0. Personal use, research, modification, non-commercial sharing, internal use and commercial use of the outputs are allowed. “Selling or commercially bundling the model, operating a commercial model service, or offering an independent commercial coding or office assistant using it requires a separate written Edge0 license.”
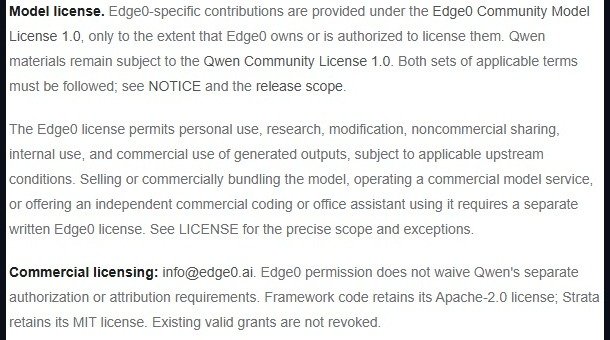
App developers: if you already point a client at an OpenAI-style URL, the card says this server speaks that protocol. We did not test your client.
Creators and solo founders: use it for your own work and sell what it produces, subject to the upstream Qwen terms. Do not build a paid assistant on top of it without Edge0’s written licence. On a 5090 D the card reports 98.3 tok/s agent decode (NVFP4).
Game devs: the Edge0 blog shows its own demos of playable games and a medieval city built in Blender. We did not verify or reproduce them. Treat them as marketing until someone else does, and only consider it if you already own a 24 GB card and the RAM listed above.
Caveats
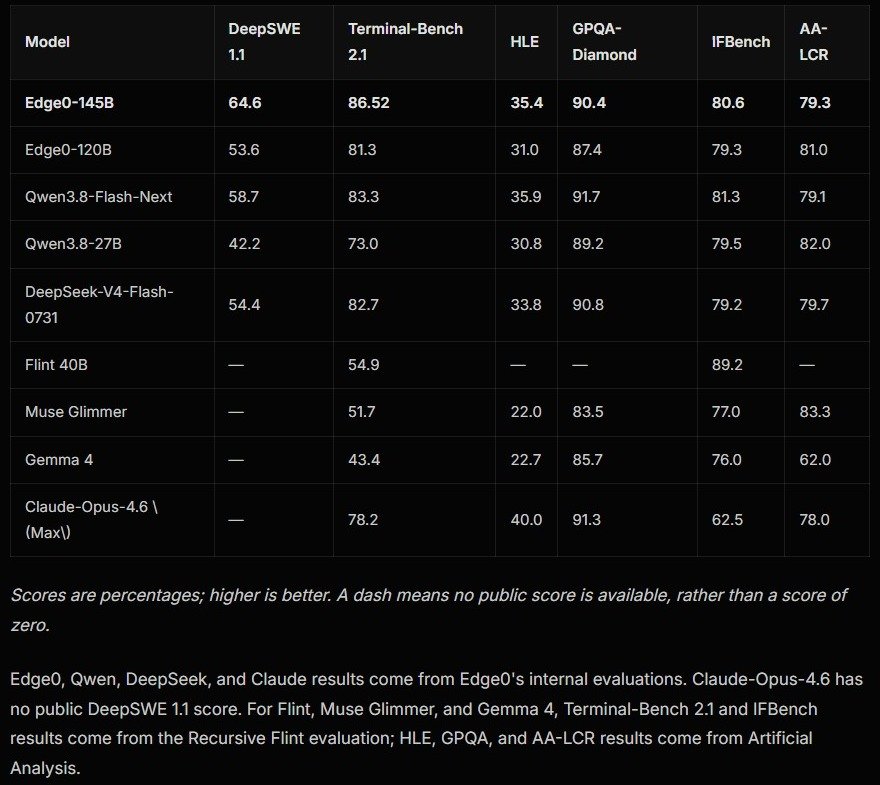
- Benchmarks are Edge0’s own. “Edge0, Qwen, DeepSeek, and Claude results come from Edge0’s internal evaluations”, and the technical report is “being released”.
- On Terminal-Bench 2.1 Edge0 scores 86.52 against 83.3 for Qwen3.8-Flash-Next. On HLE it scores 35.4 against 35.9, and Claude-Opus-4.6 Max scores 40.0.
- The rival memory figures (Qwen about 70GB, DeepSeek about 87GB) are estimates that “remain to be measured”.
- The card says Edge0 is “not a relabelled Qwen3.8-Flash-Next, and not a re-quantization of it”.
Our take
Interesting weights, honest speed table, loose headline. If you have a 24 GB GPU and plenty of RAM, it is worth a look. If you have a regular laptop, wait for independent tests.